Ornymo
Semantic caching reduces LLM token costs and latency for AI queries.
★ 0.00 reviews
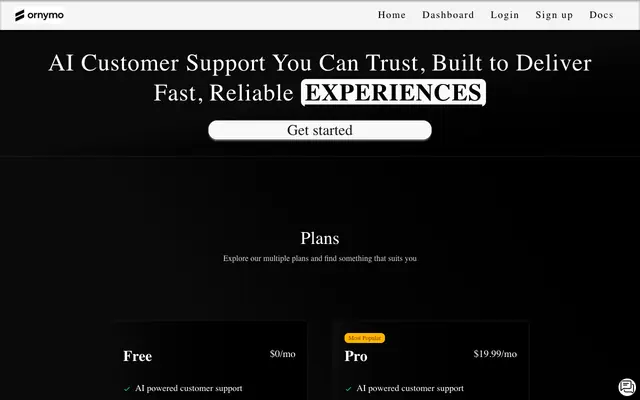
Details
Semantic caching reduces LLM token costs and latency for AI queries.
Discoverer: Awesome Vibe-Coded Apps
Recent reviews
No reviews yet
Semantic caching reduces LLM token costs and latency for AI queries.
Semantic caching reduces LLM token costs and latency for AI queries.
No reviews yet